1. The Empirical Bottleneck in Conventional Biologics Discovery #
For over three decades, therapeutic monoclonal antibody (mAb) discovery has relied on two stochastic biological engines: in vivo animal immunization (hybridoma or transgenic humanized mice) and in vitro display libraries (phage, yeast, or mammalian surface display). While these platforms have delivered more than 160 FDA- and EMA-approved biologics, they remain fundamentally constrained by immunodominance and physical library size ceilings.
In a typical immunization campaign targeting a multipass transmembrane protein—such as a G-protein-coupled receptor (GPCR), an ion channel, or claudin-18.2—the host immune system overwhelmingly generates antibodies against exposed, hypervariable extracellular loops rather than conserved, functionally critical catalytic clefts. Even large synthetic phage display libraries, which physically sample 1010 to 1011 variants, cover less than 10-15 of the theoretical sequence space across the six complementarity-determining regions (CDRs).
Wet-Lab Validation Note — Dr. S Paul, Chief Scientific Reviewer: "A generative diffusion model will happily hand you a CDR-H3 loop with four consecutive tryptophan and phenylalanine residues because hydrophobic packing maximizes the in-silico docking score. Put that construct into transient HEK293 expression, however, and it sticks to the SEC column like glue. Never synthesize an AI-generated mAb panel without running a surface-exposed hydrophobic patch filter first."
Consequently, discovery teams routinely spend 24 to 36 weeks executing iterative panning, primary ELISA screening, and Sanger or NGS sequencing, only to discover during late-stage biophysical triage that their highest-affinity leads suffer from severe conformational instability, high-concentration viscosity above 20 cP, or off-target polyreactivity.
2. Computational Architecture: Equivariant Diffusion Meets Paired Repertoire Language Models #
Modern generative biology architectures bypass stochastic library panning by formulating antibody design as a conditional 3D inverse-folding and sequence-co-generation problem. Instead of screening random variants blindly, generative pipelines integrate two complementary foundation architectures:
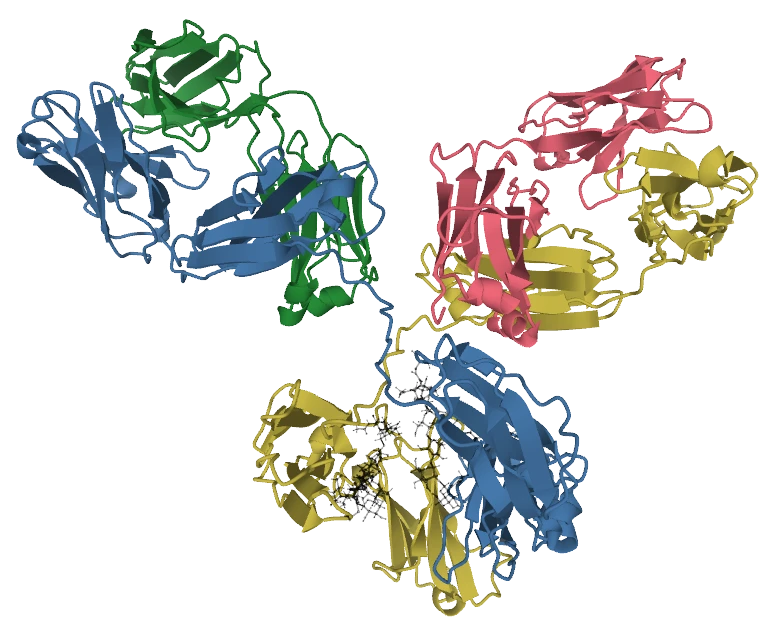
- SE(3)-Equivariant Backbone Diffusion Models: Derived from structural diffusion frameworks (such as RFdiffusion-Antibody, Chroma, and proprietary geometric deep-learning engines), these models treat the target antigen’s atomic coordinates and electrostatic surface potential as fixed boundary conditions. The network denoises random 3D atomic coordinates directly around a user-specified cryptic or allosteric epitope, generating physically valid heavy-chain (VH) and light-chain (VL) backbone geometries with atomic-level steric complementarity.
- Paired Antibody Protein Language Models (pLMs): Unlike generic protein models trained on monomeric microbial sequences, antibody-specific language models (trained on over 2.4 billion native B-cell receptor sequences from OAS and deep repertoire sequencing cohorts) capture subtle somatic hypermutation (SHM) co-evolutionary couplings between framework regions (FR1–FR4) and hypervariable loops.
- All-Atom Side-Chain Packing & Thermodynamic Scoring: Once the backbone and CDR sequences are co-generated, neural energy functions evaluate buried solvent-accessible surface area (ΔSASA), hydrogen-bond network satisfaction across the paratope–epitope interface, and free-energy perturbation (ΔΔ Gbind) prior to gene synthesis.
"The industry shift is no longer about predicting static apo-structures in isolation; it is about conditioning generative models simultaneously on sub-nanomolar binding kinetics, human germline humanness, and 150 mg/mL subcutaneous formulation stability from Day 1."
3. Zero-Shot CDR-H3 Redesign & Active-Learning Wet-Lab Benchmarks #
The decisive test of any in silico biologics platform occurs at the wet-lab bench. Across the six CDR loops, CDR-H3 exhibits the widest length distribution (ranging from 5 to over 26 amino acids) and extreme conformational plasticity, frequently undergoing induced-fit rearrangement upon antigen engagement.
In recent multi-target benchmarking campaigns across oncology and autoimmune targets, pure "zero-shot" generative designs—sequences synthesized directly from computational predictions without prior wet-lab training data on the specific target—achieved confirmed surface plasmon resonance (SPR) binding hit rates between 4.5% and 14.2%. While a 10% zero-shot hit rate already represents a 100-fold enrichment over random mutagenesis, the true inflection point emerges when generative models are coupled to a Design–Build–Test–Learn (DBTL) active-learning loop.
| Discovery Performance Metric | Conventional Phage / Hybridoma Campaign | Zero-Shot De Novo AI Generation | Active-Learning AI + HT-SPR Loop (2 Cycles) |
|---|---|---|---|
| Target-to-Validated Lead Timeline | 24 to 36 weeks | 3 to 4 weeks | 6 to 9 weeks |
| Variants Physically Synthesized & Screened | 10,000 – 50,000 clones (ELISA) | 96 – 384 gene fragments | 384 – 1,536 gene fragments |
| Confirmed Functional Binder Hit Rate | 0.4% – 1.8% of primary picks | 4.5% – 14.2% (KD < 100 nM) | 22.0% – 38.5% (KD < 5 nM) |
| Picomolar Affinity (KD < 500 pM) Clones | Requires 3–4 months of error-prone PCR | Rare (< 1%) | 6.5% – 12.0% in Cycle 2 |
| Subcutaneous Developability Pass Rate | sim 30% (high late-stage attrition) | sim 78% (in silico filtered) | > 92% (multi-objective pareto front) |
In a 2-cycle active-learning workflow, 384 diverse CDR-H3 and CDR-L3 designs are synthesized as linear dsDNA fragments, expressed transiently in high-throughput 24-deep-well CHO or HEK293 formats, and assayed directly from clarified supernatant on 384-spot High-Throughput Surface Plasmon Resonance (HT-SPR) arrays. Both positive kinetic curves (kon association rates above 105 M-1s-1 and koff dissociation rates below 10-4 s-1) and confirmed negative non-binders are fed back into a Bayesian surrogate head to fine-tune the generative model for Cycle 2.
4. Multi-Parameter Developability Triage: Eliminating Late-Stage CMC Failures #
A high-affinity binder is clinically useless if it aggregates into immunogenic particulates during downstream tangential flow filtration (TFF) or exhibits rapid systemic clearance due to non-specific neonatal Fc receptor (FcRn) or heparan sulfate proteoglycan binding. To prevent late-stage Chemistry, Manufacturing, and Controls (CMC) attrition, modern AI pipelines enforce five mandatory in silico and high-throughput biophysical filters before advancing any clone to cell line development:
- Spatial Aggregation Propensity (SAP) & Hydrophobic Patch Masking: Algorithms map solvent-exposed aromatic and aliphatic residues (Trp, Tyr, Phe, Ile, Leu) across the 3D paratope surface, substituting non-essential hydrophobic residues with polar or charged amino acids to keep High Molecular Weight (HMW) species below 1.5% by SEC-HPLC.
- Isoelectric Point (pI) and Net Charge Symmetry: Maintaining the variable-domain net charge between +1.5 and +4.5 at pH 7.4 prevents both extreme electrostatic self-association (high viscosity in autoinjector syringes) and excessive pinocytosis in vascular endothelial cells.
- Sequence Liability Eradication: Automated motif scanners eliminate unpaired cysteines, N-linked glycosylation sequons (N-X-S/T) within CDR loops, deamidation-prone NG/NS motifs, and isomerization-sensitive DG/DS dipeptides.
- germline Humanness & MHC-II Immunogenicity De-risking: Deep neural predictors score framework and CDR junctions against human IGHV/IGKV repertoires (requiring >88% OAS humanness scores) while screening 15-mer overlapping peptides against HLA-DRB1 alleles to minimize anti-drug antibody (ADA) clinical responses.
- High-Throughput Biophysical Confirmation: Synthesized leads undergo Affinity-Capture Self-Interaction Nanoparticle Spectroscopy (AC-SINS, requiring Δlambdamax < 5 nm), Differential Scanning Fluorimetry (Tm1 > 68°C), and Baculovirus Particle (BVP) polyreactivity ELISA.
5. Enterprise Data Governance: Consolidating LIMS, ELN, and Entity Registries #
As biopharmaceutical R&D organizations and contract discovery partners scale generative AI across multi-site discovery operations, data architecture—not GPU compute—has emerged as the primary operational bottleneck. Legacy workflows that store phage panning titers in Excel spreadsheets, SPR sensorgrams on local instrument hard drives, and sequence alignments in disconnected FASTA files starve machine learning models of structured training context.
Leading biologics enterprises are replacing fragmented file shares with unified, cloud-native Scientific Entity Registries (LIMS + ELN) that enforce FAIR (Findable, Accessible, Interoperable, and Reusable) data ontologies:
- Automated Instrument Telemetry: Direct SiLA-2 and REST API connectors stream raw sensorgrams from Biacore/Carterra SPR systems, Octet BLI platforms, CE-SDS electropherograms, and UPLC-MS intact mass spectra directly into structured relational database schemas linked to unique plasmid and protein batch IDs.
- Capturing Mandatory Negative Data: Machine learning models require balanced decision boundaries. Recording exact experimental metadata for clones that failed expression (<10 mg/L), precipitated upon Protein A elution (pH 3.5 viral inactivation), or showed non-specific tissue cross-reactivity prevents generative algorithms from repeatedly exploring unviable biophysical regions.
- In-Platform AI Co-Scientists: Natural-language query layers built directly atop unified ELN/LIMS graphs now allow bench immunologists to query historical cross-program datasets, automatically assembling multi-objective Pareto fronts across affinity, cross-species cynomolgus monkey reactivity, and thermal stability in seconds.